
De veiligheidscirkel heeft het over Agenetic SOC: CrowdStrike.
In the last six months, the most frequent word for the safe circle conference table, the manufacturer's launch, and the A-CISO friends' circle is probably Agentic SOC. And what really defines this word as a narrative of industry is CrowdStrike. And the problem follows: who is responsible for what happened when the SOC gave AI an automatic diversion of the police and a determination of malice? CrowdStrike, how dare you let AI judge?
See background first: Response window from week to second
CrowdStrike's judgment in Fall 2025 is that the attackers are in the process of AIization, that breaktime (breakout time) has been reduced from hour to minute, and that the analyst's response window has been compressed. Every day, the SOC team was flooded in police, individual workers and repeated investigations — falsely reported by the tactical sequence of the people — and could no longer escape the machine's attack. It's a line of pressure that's being put on by an agentic SOC: not to have AI replaces, but people can't handle it.
Eerste onderkant: miljoenen trainingsgegevens voor de besluitvorming door deskundigen
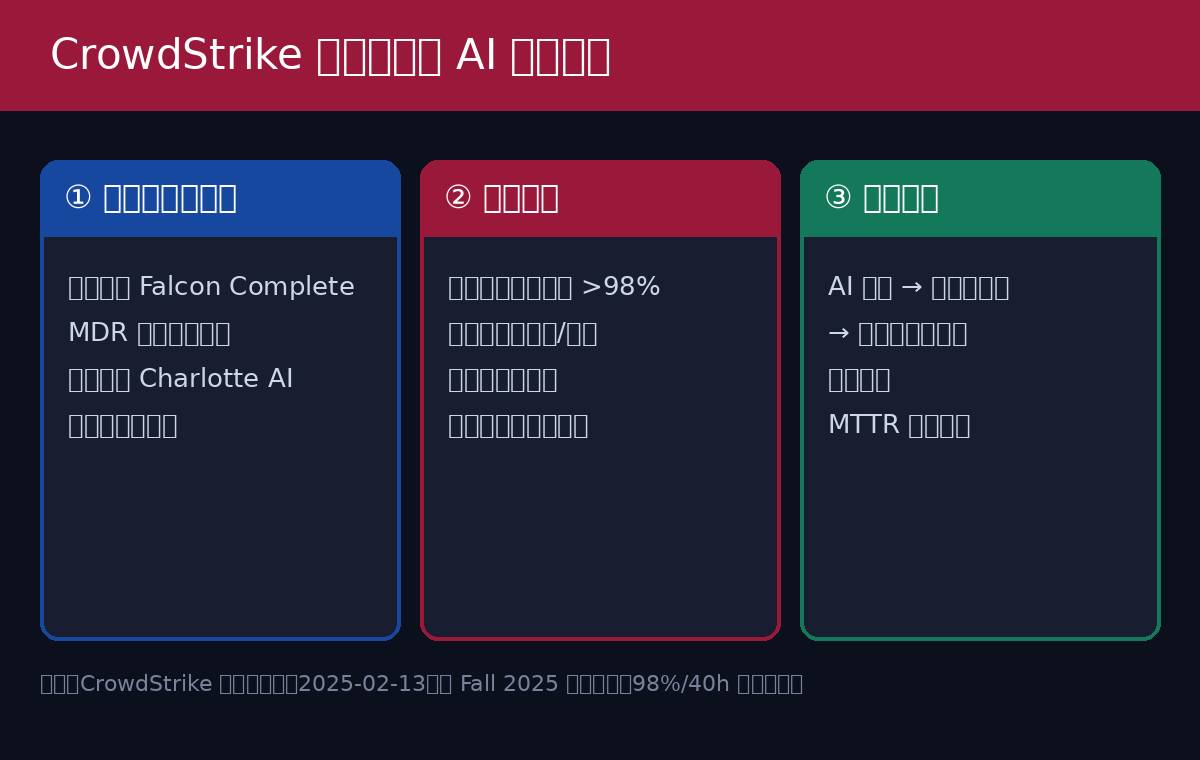
Let AI judge, the worst fear is that the quality of the judgement is unfounded. The answer given by CrowdStrike is hidden in its least visible asset: Falcon Complete Next-Gen MDR service. Over the past 10 years, this “gold standard” hosting testing and response team has made millions of manual sorting decisions in the real client environment — each of which is a counter-sampling sample with an expert label.
Charlotte AI was trained with these data, not the generic Internet language. Officially, in the Detection Triage press release, it was stressed that, unlike generic models trained in a broad knowledge base, Charlotte AI was based on proprietary datasets and was based on real rival tactics. In other words, it dared to let AI learn to board because AI learned from first-line security experts years of cumulative judgement itself. This is the first ring of the data wheel: the training data are from human experts, not the public text.
Second base: Bounded Autonomy, borders drawn by clients
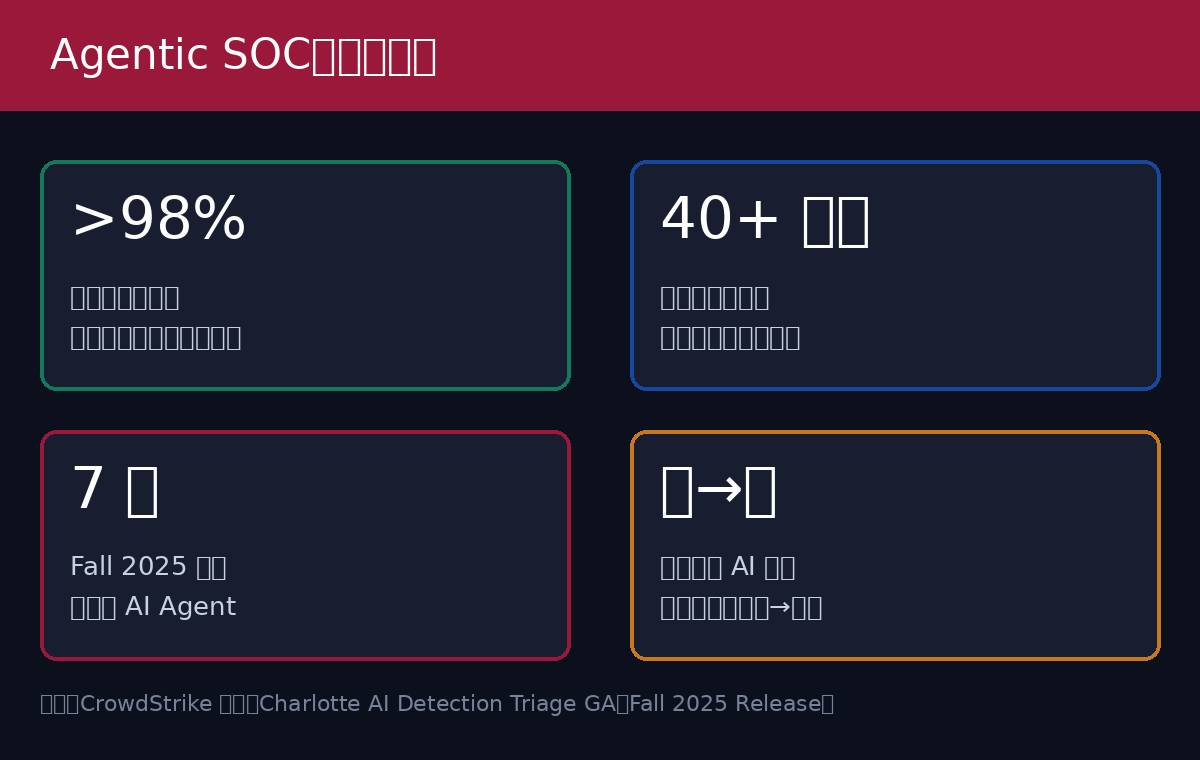
This is the most critical engineering design in the whole story. In February 2025, Charlotte AI Detection Triage of GA, the official calibration is that it operates under a client-defined model of territorial autonomy, with an accuracy rate of over 98 per cent for detection of consultations and an average of SOC elimination of manual work of more than 40 hours per week.
Note that the word "there's a bound" is not AI: it's the security team itself that defines when and in what way automated actions are allowed to occur — from the diagnosis to the final response, inside the fence, where humans retain full oversight. CrowdStrike CTO Elia Zaitsev's statement is straightforward: let the organization “control when and how it automates, and keep AI credible, accountable and under human agency”.
The design responds to one of the biggest concerns of the A: it's not AI, it's whether or not something happened. Low-risk alerts with high confidence allow AI to turn off direct; disposal actions (segregated hosts, blocked accounts) are upgraded to human approval. AI does "in your line of discretion" and not "unmanned".
Third base: the analyst's review constitutes a closed loop, the more accurate it is.
Autonomy also brings with it a by-product: every human review, overthrow, correction of AI's judgement is translated into a new training signal, which is officially referred to as a closed loop feedback process to continuously improve safety outcomes. AI judgement → expert calibration → data backfilling, model constantly approaching specialist level in human collaboration. And that's why CrowdStrike in Fall 2025 moved the analyst's position from "operator" to "orchestrator" — one who directs an agent fleet of reasoning, decision-making, action, not human filtering.
 Data Layer and Agent Legion: Not enough to judge.
Let AI judge if AI understands the whole picture. In Fall 2025, CrowdStrike synchronized three puzzles:
- Bedrijfsgrafiek: Unified endpoint, identity, cloud, SaaS, XIOT and third-party tool telemetry AI-ready data layer, officially known as “the industry's richest AI-ready data layer”, with a single query language, in which both people and delegates can call every signal immediately.
- Zeven takenExposure priority, malicious software analysis, threat hunting, associated rules generation, search analysis, workflow generation, data conversion - corresponding to the seven most labour-intensive processes in SOC.
- Charlotte AI AgentWorks2026 On-line ecology in March 2026: allow safety teams to build, test, deploy and manage their own enterprise-level governance in natural languages; hand over the capacity to build an agent to the client himself.
Add Threat AI (the self-proclaimed industry's first proxy threat information system), Agency MDR (published in RSA 2026, Falcon Complete analyst personally designed the intelligent body to counter the accelerating threat of AI), and AIDR (AI detection and response, which in turn protects the firm's own AI) - the complete logic of "bringing" is based on judgement, data, organization, governance.
Rustig: 98% is een fabrikant.
It is worth recalling that 98 per cent of the accuracy rate, 40 hours per week in the province of CrowdStrike, officially stated that data based on its internal assessment and client collaboration had not been independently validated by third parties. The cost of security decision-making is naturally asymmetric: the cost of ignoring a positive is much higher than the cost of over-reporting. So the industry’s current consensus stance is to leave "Ai" sorted, diverted, abstracted" high-end fault lines, leaving "Closure, Handling, Qualification" to human approval within a framework of autonomy. Actic SOC is not an unmanned driver, but an automatic driver with a guard watching.
A little observation.
CrowdStrike's Dare, which is essentially a 10-year MDR data accumulation plus autonomous engineering design + human-closure box. What it really sells is not “AI will judge”, but “AI will be calibrated by experts, within the boundaries you have drawn, and by humans in every case”. In the case of the A, the list of assessments of agentic SOC can also be followed by the three articles: where did the training data come from? Who defines the boundary? How do you turn the ring?