
GPT-6.1 Terra, not a broken price, but this one finally made up the middle.
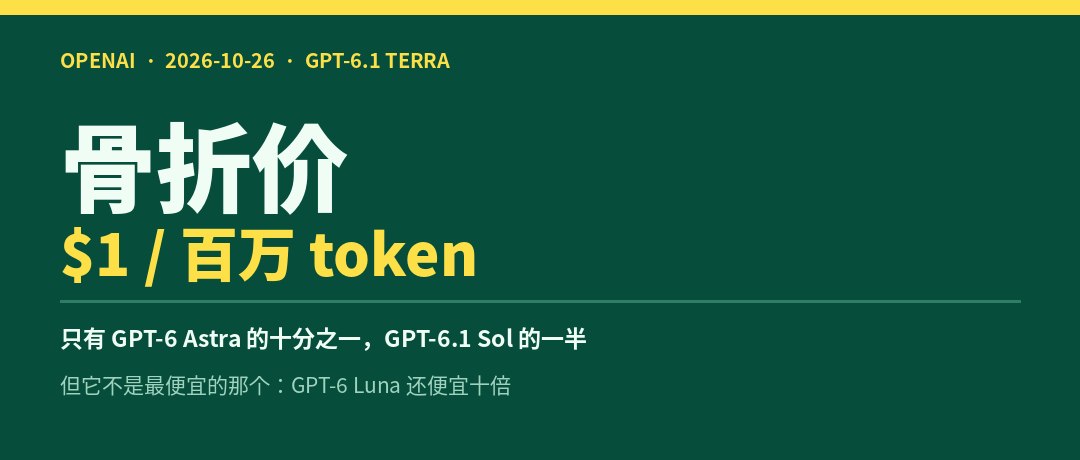
First, the conclusion is that:GT-6.1 Terra is really cheap, $1 input / $5 output, which is exactly half the GPT-6.1 Sol cut. But it's not a "break," it's a "re-horizon."And it's not the cheapest model in the world -- the same price list is down, ten times cheaper.
If you don't figure out these two things, you change models in the wrong direction: you think you're picking up leaks, and you're squeezed to the middle.
First, break the word.
It's the official saying: standard API price ratio GPT-5.6 Terra and GPT-6.1 Sol 50% low.
This contrast is very well chosen. Sol, yes. $2 / $10I'll cut it in half. $1 / $5The numbers are right. But it was used as an anchor in GPT-5.6 Terra.I can't find it on this flag list anymore.I don't know. I went through the pricing page, and there were only four flags left: Astra, 6.1 Sol, 6.1 Terra, and 6 Luna.
In other words, it's not a price reduction for the same model."with a new, cheap model, replacing an old model that's already down."I don't know. The two matters are completely different in terms of procurement: the former is the savings of the stock of customers, and the latter is the voluntary relocation.
There's another, even less mentioned:It's not the cheapest of them.
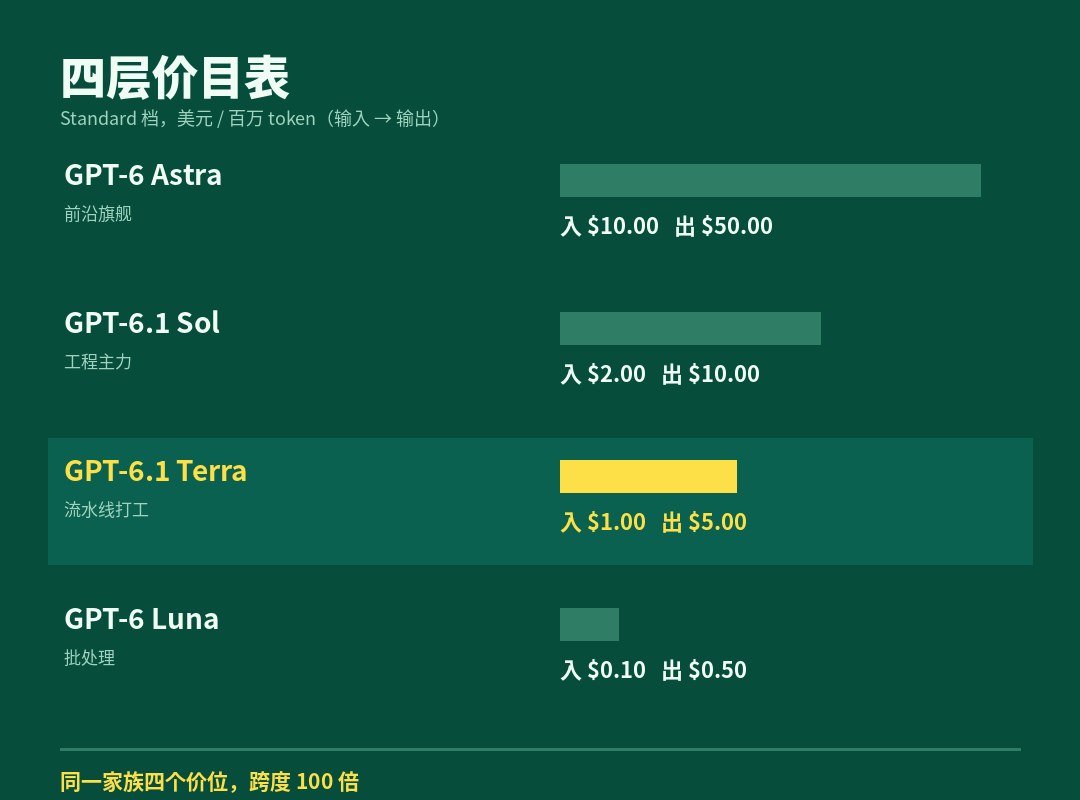
II. Four-tier price list, 100-fold range
Level up the Standard file, this is what it looks like.
| Model | Input | Output | Cache Input | Positioning |
|---|---|---|---|---|
| GPT-6 Astra | 10.00 | 50.00 | 1.00 | Front flagship |
| GPT-61 Sol | 2.00 | 10.00 | 0.10 | Major engineering |
| GT-6.1 Terra | 1.00 | 5.00 | 0.05 | The water line works. |
| GT-6 Luna | 0.10 | 0.50 | 0.01 | Batch |
Enter price difference from Astra to Luna 100 timesI don't know. Terra is stuck below the center.Ten times cheaper than it is, Luna. It's just down the line.It's just an official note that says nothing.
So the term "break price," exactly."A lower price in the middle."I don't know. The real effect of this is to replace the original "either with an expensive flag ship or with a good old money" with "a useful slot in the middle."
It's good for the people who do Agent, and it's good. But don't interpret it as "the lowest on the web."
iii. Its location is actually written in the title: Work model
There's an exact word in the official description... It's good at "the communications and computer operations that fill out the workdays": drawing up programs, looking at technical drawings, filling out forms, cutting videos.
Note the common denominator of these four examples:"Don't be stupid, don't be too slow, don't be too expensive."
That's exactly what Agent's water line really needs. The Agent, who runs backstage and calls thousands of times a day, does not need the Osei King, but the steady hand and cheap bill. That's what Terra came for.
The most significant indication of this is speed:More than three times faster than GPT-6 Astra and GPT-6.1 Sol.
It's almost three times as valuable as the Agent scene. A multi-step, 10-wheel-drive tool is called, two seconds behind each wheel, and the whole mission is 20 seconds longer — users don't know "models are smarter" but "how is it not good?"
Four, which ones are really up in the run?
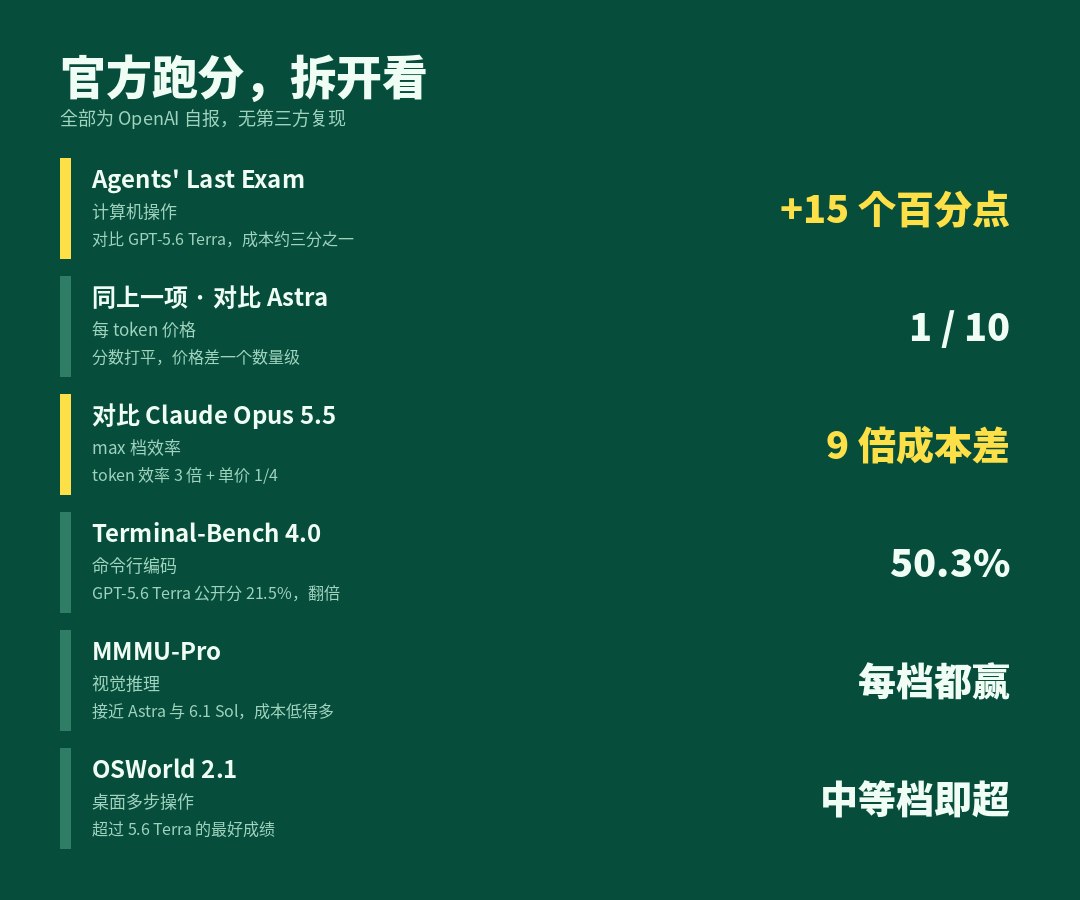
I took a look at the six official benchmarks and put them in a "credibility" line.
Really high: error rate
This number is of the utmost importance to me: in the test set for "inducing error" inside it, it's the most important thing to do.The error rate in the low-debate file dropped from 53.6% to 16.7%.This represents a decrease of almost 37 percentage points; the highest tranche fell from 22.3 per cent to 4.3 per cent.
Why is this more important than running? Because in the Agent scene,The wrong cost is not to try again, it's to roll back.I don't know. A form, Agent, misfilled the amounts, followed by manual review, reconciliation, refunds, all of which were real hours. The error rate fell from half to one sixth, which is a qualitative change.
Real lift: command line encoding
Terminal-Bench 4.0, highest reasoning 50.3%Compared to GPT-5.6 Terra, 21.5 per cent, more than doubled.
The scale of this increase is somewhat questionable, but it is in a reasonable direction: half of the mission runs, indicating that it can really read mistakes, change orders and run again. It's 50% of the water level that's barely "can be put in the CI."
The discount: the match.
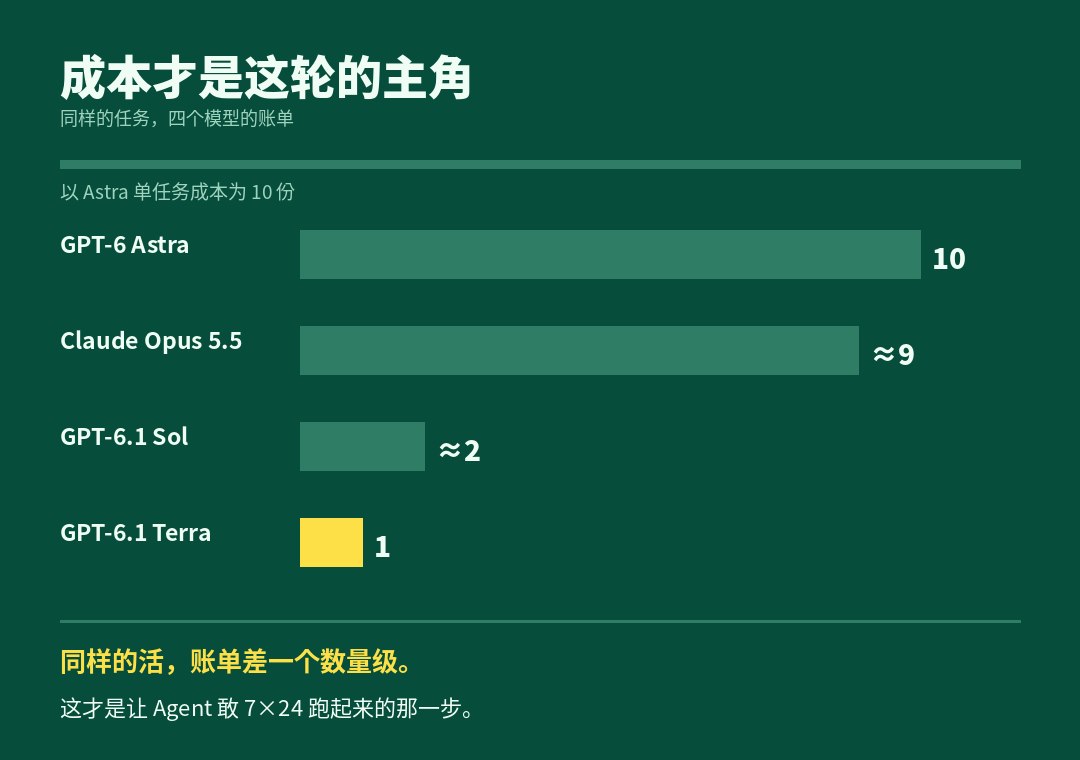
"3 times more efficient than the token of Claude Opus 5.5, with a unit price of about one quarter, and nine times less than the cost of a single mission." I'll forget that.3 x 4 = 12, officially about 9 timesI don't know.
The difference is probably due to the distribution of the tasks and the cache rate, which was rounded up by the official "about." It's not fake, but you need to know.The compound factor is multiplied. Any caliber changes, the conclusion changes.I don't know. See the number "9 times" and ask which two it's on.
Unverifiable: All
All the above numbers,All from OpenAI self-report, no third party to repeat.I don't know. LMArena has no place on it, and the independent monitoring agency has no time to run. For this type of publication, I usually treat self-rating as "ceiling" and third parties as "real".
It's not the price, it's the small word.
When I read the statement, I turned to the section on security and alignment, and I saw a saying that many people would sweep through:
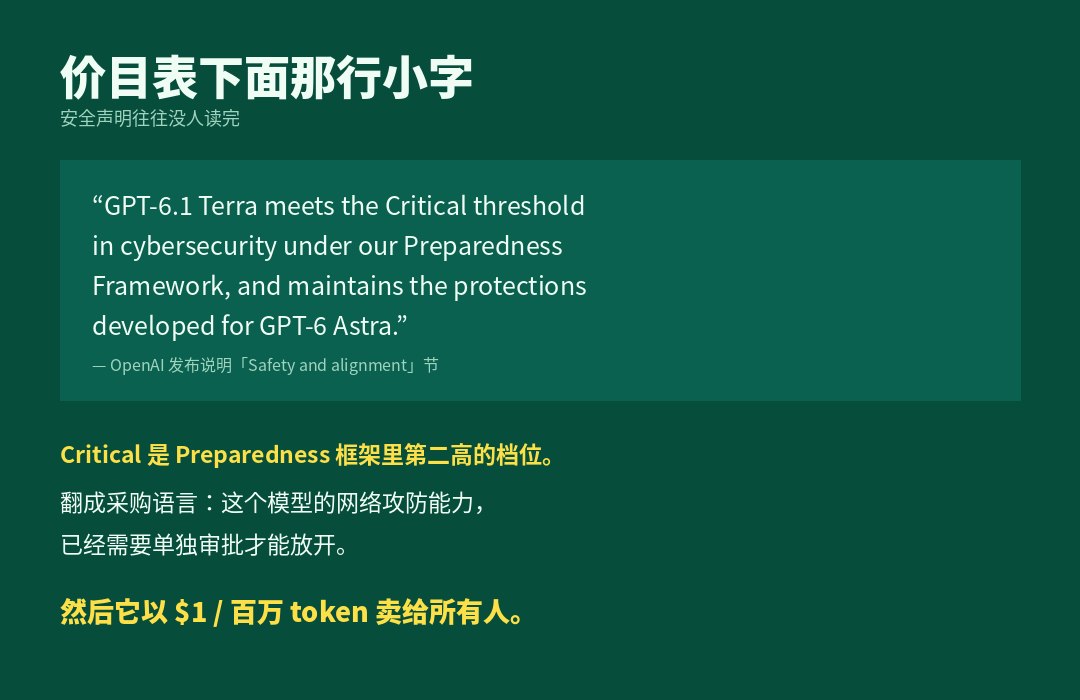
"GPT-6.1 Terra, within our Preparedness framework, reaches the Internet-safe Critical threshold and maintains the protections developed for GPT-6 Astra."
Critical is the second highest slot in this framework -- there's only one "higher than Critic" on it. Translation into procurement language:The model ' s cyber-control capability has crossed the line that needs to be assessed separately and controlled separately.
And then it sold to everyone for $1/million token.
It's okay to look at both things alone. It's fun to read together:A model marked by its own safety framework as "Critical Level Network Capability" is now the most cost-effective generic model in the family.
I'm not going to say "AI danger" here. It doesn't make sense. But if you're in charge of security, there's a specific question to answer:When any of the companies develop a model that can use a cup of coffee to build a network capability at the Cristical level, what's your border line?
The answer to the Microsoft framework last week was to take the permissions from the model. This pricing, Terra, is a further push for the urgency of this answer:Capacity is where inflation, prices deflation, and where the two curves intersect, is where control has to land.
Six, who should change now, who shouldn't.
I should have.
- Run a batch document processing.Reading invoices, filling out forms, extracting contract terms - tasks of this kind are low on "smart" and high on "stability + cheap". $1 input price plus 16.7% error rate, which is currently dessert.
- Do multistep GUI automated.OSWorld 2.1 has outperformed the best results of the previous generation, while the worst thing about GUI automation is slow and expensive.
- This post is part of our special coverage Global Voices 2011.What you need is a model that runs 100,000 times a day and doesn't hurt. It's not a model that can write poems, but 30 cents at a time.
Don't hurry.
- Do the most complex coding tasks.The official himself said that the hardest coding was Sol and Astra. Terra's 50.3% is "half can pass", not "all pass."
- Already Depthed Sol's.Instead of changing the model, we're done -- hints, tool descriptions, retrying strategies, tailoring the context. Save that token money, maybe not enough manpower for two days.
- To issue a compliance report.No third party has reproduced it, and your assessment report does not say "independently certified".
There is also one special case:If your business is small, this price drop is almost meaningless to you.Hundreds of calls a day, down from $2 to $1 a month less than enough to buy coffee. This list is for big teams.
VII. Final sentence
This round was published under the title "Breaking Price," but I think the real signal is three more:
- The middle is done.There was only a "flagship" and a "compatibility" series, and now there is a clear "fit and cheap". It's structurally good for the whole Agent ecology.
- The price fight reached the third level.When the prices of the first two families dropped, the flag ships were cut; this time, the main gear. As soon as the main gear drops, the small models that live on "cheap" are out of place.
- The capacity and price of scissors is increasing.Critical-level network capacity + $1 pricing, a combination that is not a single problem, but a whole chain of industries.
The cheaper the model, the more Agent; the more Agent, the more it can be automated. It's not an emotion. It's a arithmetical question.
As for Terra itself: it's a good model, and the price is really bad.But it's not a fracture, it's the one that finally made up the middle.What you're going to do is not rush in, you're going to look back at your pile of Agent, which should have been done by a cheap, stable, three-fold worker.
Change it, save more than you think. The rest should be done by flag ships — not to save money for a working model to do the job of Director General.